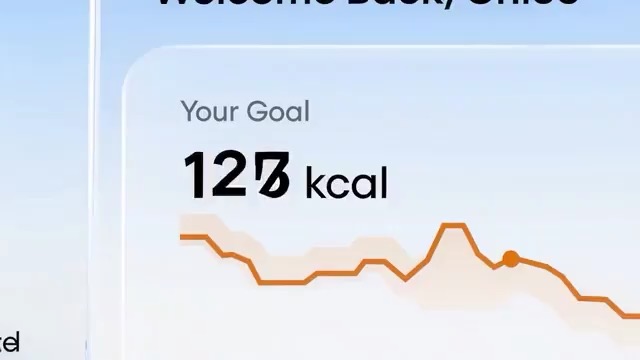
SaaS feature loop storyboard preview showing an app screen, cursor motion, value reveal, and loopable final hero frame.
SaaS feature loop storyboard: app context / user action / UI transition / value reveal / loopable hero frame / review checks
Seedance 2.0 is Rivya's fuller Seedance AI video generator for text-to-video, frame-guided animation, multimodal references, and more polished scene output than Fast.

Example output
Example; generating model unverified · Preview for a SaaS feature loop storyboard, focused on app context, UI transition path, readable copy, editable metrics, and the loopable final frame.
Text to Video · Image to Video

Example output
Example; generating model unverified · Preview for a SaaS feature loop storyboard, focused on app context, UI transition path, readable copy, editable metrics, and the loopable final frame.
Best for
Supports
Online trial
No result yet. Submit a prompt to start a run.
Prompt starters
Model proof
Use the online trial above, then compare these example results to judge finish, rhythm, and task fit before you spend more credits in Studio.
Lead sample
SaaS feature loop storyboard preview showing an app screen, cursor motion, value reveal, and loopable final hero frame.
Input
Prompt, frames, or image/video/audio references
What to notice
SaaS feature loop storyboard preview showing an app screen, cursor motion, value reveal, and loopable final hero frame.
Credits per use
per_input_and_output_second · 720p_without_video=41 · 1080p_with_video=62 · 1080p_without_video=102 · 4K_with_video=128 · 4K_without_video=208 · ⌈total⌉
Why this model works
Full Seedance 2.0 scene split: text, frames, and multimodal reference
Prompt-led, frame-led, and multimodal reference projects in one model
Optional synced audio generation and returned final frame
Best-fit tasks
Model proof
Decision fit
Decision fit
Seedance 2.0 FAQ
Use Seedance 2.0 for higher-quality short videos from prompts, start and end frames, or multimodal reference bundles. It is the full Seedance 2.0 option when image, video, and audio references need to guide one clip and clearer motion control matters more than the Fast tier's lower cost.
On Rivya, Seedance 2.0 currently supports text to video, image to video, and reference to video. If the task needs live research grounding, that is already part of the public control set here.
Choose Seedance 2.0 when prompt-led, frame-led, and multimodal reference video projects need to stay in one model while keeping their input rules separate. If you are still narrowing down the direction, start with a lighter draft option.
Start here when the first run is aimed at higher-quality short videos from prompts, frames, or reference bundles, frame-constrained motion design where start and end images matter, and multimodal reference synthesis with image, video, and audio inputs. That keeps the first run practical: check the input, direction, and output quality here before turning it into a longer project.
This page currently supports text to video, image to video, and reference to video. That makes it easier to see whether a pure shot description or a still-led start is the better way into higher-quality short videos from prompts, frames, or reference bundles.
Stay on this page while you are still validating the first shot, source type, and whether the first result is getting you close to higher-quality short videos from prompts, frames, or reference bundles on Seedance 2.0. Open the full Studio once the work needs saved versions, repeated clip iterations, multiple assets, or a longer production thread around the same scene set.
Compare alternatives
Seedance 2.5 is Rivya's larger Seedance workflow for prompt-only video, first- and last-frame guidance, multimodal references, and video-guided transformation. It adds a 1080p tier, output up to 30 seconds, automatic duration, MP4 or MOV output, and substantially larger image, video, and audio reference capacity than Mini.
Why consider it
Consider it when your next task needs Up to 50 reference files.
ByteDance's faster Seedance 2.0 video model with full scene routing for prompt-only generation, frame-driven image animation, and multimodal reference video generation. Rivya keeps the documented scene split explicit so first/last-frame inputs do not collide with reference image, video, and audio roles.
Why consider it
Consider it when the credit note fits your next run: per_input_and_output_second · 480p_with_video=6.8 · 480p_without_video=11.7 · 720p_with_video=15 · 720p_without_video=24.8 · ⌈total⌉.
Seedance 2.0 Mini is Rivya's lower-rate multimodal Seedance workflow for prompt-only video, first- or first-and-last-frame animation, and mixed image, video, or audio references. Its 480p and 720p tiers cover 4-to-15-second output while keeping the three input scenes mutually exclusive.
Why consider it
Consider it when your next task needs Up to 15 reference files.
Example; generating model unverified · Preview for a polar ice anomaly reveal, focused on suspense pacing, environmental VFX, scale contrast, and a controlled final reveal.
Polar ice anomaly reveal video preview showing a research station, red emergency light, and distant ice shelf fracture.
Best-fit tasks
Use it when the task looks like this
Quiet facts
Provider
ByteDance
Category
Video
Capabilities
Text to Video · Image to Video · Reference to Video
Credit model
per_input_and_output_second · 720p_without_video=41 · 1080p_with_video=62 · 1080p_without_video=102 · 4K_with_video=128 · 4K_without_video=208 · ⌈total⌉
Input path
Prompt, frames, or image/video/audio references
Prompt setup
Up to 20,000 chars
Developer access
Call Seedance 2.0 from Public API v1 after checking the model fields, reference media rules, and credit behavior.