8-10s
UGC Product Demo Video video preview showing motion rhythm, subject continuity, camera direction, and final hero frame.
UGC Product Demo Video video brief: setup / main motion / camera path / continuity / hero ending / review checks
ByteDance's faster Seedance 2.0 video model with full scene routing for prompt-only generation, frame-driven image animation, and multimodal reference video generation. Rivya keeps the documented scene split explicit so first/last-frame inputs do not collide with reference image, video, and audio roles.
Example output
Example; generating model unverified · Preview for UGC Product Demo Video, focused on scene setup, camera path, motion continuity, editable details, and the final hero frame.
Text to Video · Image to Video
Example output
Example; generating model unverified · Preview for UGC Product Demo Video, focused on scene setup, camera path, motion continuity, editable details, and the final hero frame.
Best for
Supports
Online trial
No result yet. Submit a prompt to start a run.
Prompt starters
Model proof
Use the online trial above, then compare these example results to judge finish, rhythm, and task fit before you spend more credits in Studio.
Lead sample
UGC Product Demo Video video preview showing motion rhythm, subject continuity, camera direction, and final hero frame.
Input
Prompt, frames, or image/video/audio references
What to notice
UGC Product Demo Video video preview showing motion rhythm, subject continuity, camera direction, and final hero frame.
Credits per use
per_input_and_output_second · 480p_with_video=6.8 · 480p_without_video=11.7 · 720p_with_video=15 · 720p_without_video=24.8 · ⌈total⌉
Why this model works
Full Seedance 2.0 Fast scene split: text, frames, and multimodal reference
480p and 720p output with adaptive aspect ratio support
Optional synced audio generation and final-frame return
Best-fit tasks
Model proof
Decision fit
Decision fit
Seedance 2.0 Fast FAQ
Use Seedance 2.0 Fast for rapid ad previs, storyboard-frame motion, multimodal reference tests, and short social clips with optional native audio. It supports text, frame-led, and reference-led starts at 480p or 720p with adaptive aspect ratio.
Set the duration, choose 480p or 720p, and match the frame shape to the preview destination. For multimodal references, assign a clear role to each image, video, or audio input so the fast test answers one creative question.
Choose Seedance 2.0 Fast when you need full Seedance 2.0 Fast scene split: text, frames, and multimodal reference and 480p and 720p output with adaptive aspect ratio support. If you are still narrowing down the direction, start with a lighter draft option.
Start here when the first run is aimed at fast ad previews from prompts or storyboard frames, reference-to-video tests with image, video, and audio inputs, or short social launch clips with native audio turned on. That keeps the first run practical: check the input, direction, and output quality here before turning it into a longer project.
This page currently supports text to video, image to video, and reference to video. That makes it easier to see whether a pure shot description or a still-led start is the better way into fast ad previs from prompts or storyboard frames.
Before you run it, the main checks are duration, output tiers like 480p and 720p, and frame shape. Those are usually the pieces that decide whether the first result is close enough that you can keep iterating here toward fast ad previs from prompts or storyboard frames without making the setup heavier than it needs to be.
Stay on this page while you are still validating the first shot, source type, and whether the first result is getting you close to fast ad previs from prompts or storyboard frames on Seedance 2.0 Fast. Open the full Studio once the work needs saved versions, repeated clip iterations, multiple assets, or a longer production thread around the same scene set.
Compare alternatives
ByteDance's full Seedance 2.0 video model with explicit support for prompt-only generation, frame-driven animation, and multimodal reference generation. Rivya keeps the documented role split explicit so frame inputs and multimodal references stay mutually exclusive instead of collapsing into one ambiguous upload bucket.
Why consider it
Consider it when the credit note fits your next run: per_input_and_output_second · 720p_without_video=41 · 1080p_with_video=62 · 1080p_without_video=102 · 4K_with_video=128 · 4K_without_video=208 · ⌈total⌉.
A Seedance video model for text-to-video and image-to-video with native audio-visual sync. It supports 480p–1080p, 4–12s clips, 6 aspect ratios, dynamic or fixed lens control, optional audio generation, and lip-sync.
Why consider it
Consider it when your next task needs Prompt + optional images.
HappyHorse 1.0 on Rivya supports text-to-video, single-image animation, and multi-image reference video from one model page.
Why consider it
Consider it when your next task needs Prompt + optional images.
Example; generating model unverified · Preview for a neon highway aerial descent, focused on aerial rotation, loop-road scale, light-trail continuity, and weightless subject motion.
Neon highway aerial descent video preview showing a floating performer moving between glowing elevated roads at night.
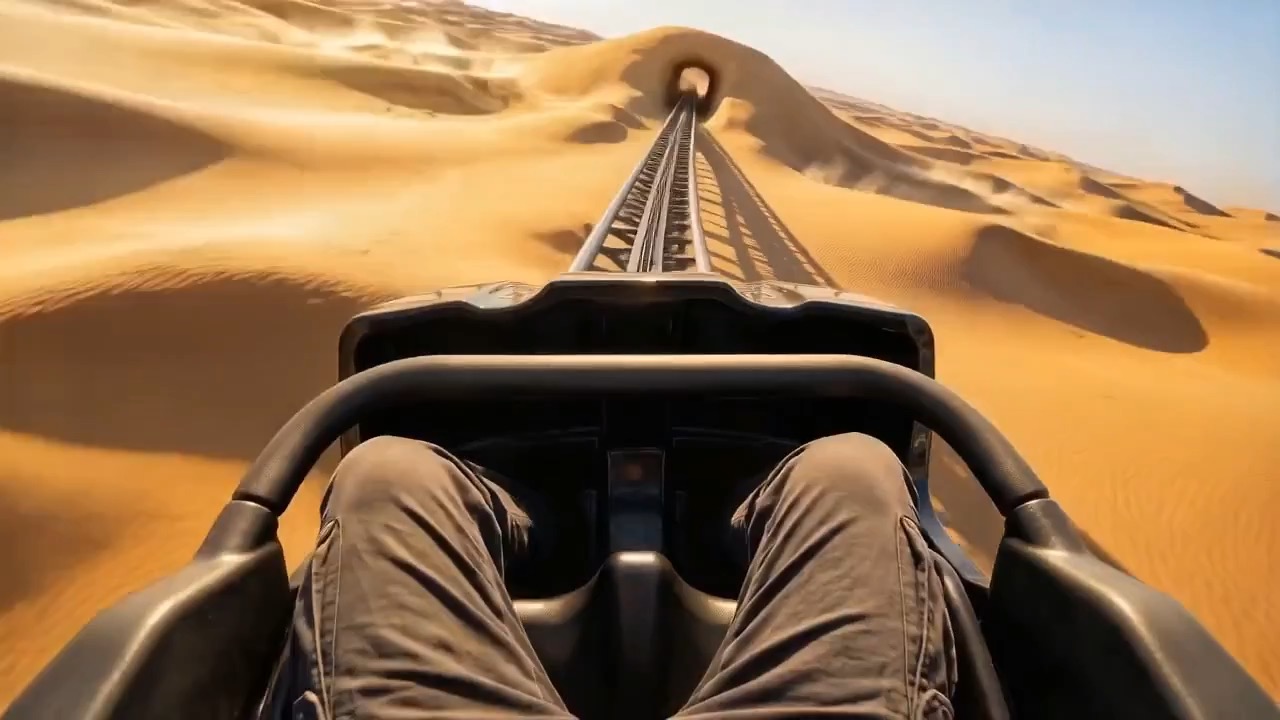
Example; generating model unverified · Preview for a first-person roller coaster POV ride, focused on continuous motion, track readability, speed changes, and natural scene transitions.
First-person roller coaster POV video preview showing the track ahead from a front-seat point of view.
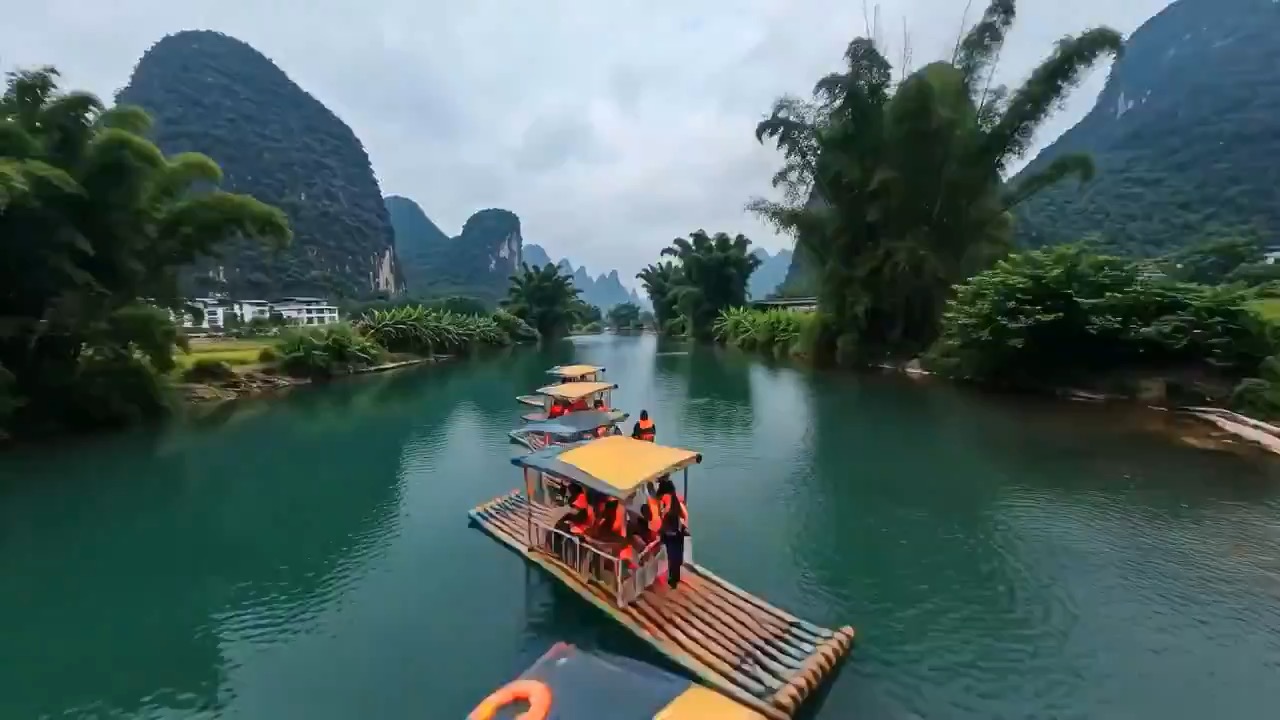
Example; generating model unverified · Preview clip for a misty karst river raft travel brief, focused on aerial scale, raft continuity, mist density, and a calm sunset panorama.
Misty karst river travel preview showing a bamboo raft moving through foggy peaks and golden river light.
Best-fit tasks
Use it when the task looks like this
Quiet facts
Provider
ByteDance
Category
Video
Capabilities
Text to Video · Image to Video · Reference to Video
Credit model
per_input_and_output_second · 480p_with_video=6.8 · 480p_without_video=11.7 · 720p_with_video=15 · 720p_without_video=24.8 · ⌈total⌉
Input path
Prompt, frames, or image/video/audio references
Prompt setup
Up to 20,000 chars
Developer access
Seedance 2.0 Fast has callable Public API modes, but reference-media modes still need Files API upload support. Check the model reference before submitting.