5.12 sec
Steampunk Chef Feast Film video preview showing motion rhythm, subject continuity, camera direction, and final hero frame.
Steampunk Chef Feast Film video brief: setup / main motion / camera path / continuity / hero ending / review checks
Wan 2.7 Video is Rivya's newer Wan AI video model for text-to-video and image-to-video drafts where you want current Wan motion quality, prompt control, and short-form scene exploration. — prompt ≤ 5000; negative_prompt ≤ 500; image: JPG/PNG/WebP ≤ 30 MB; video edit: 1 MP4/MOV ≤ 30 MB + 0–1 image.
The final task cost is rounded up to whole credits.
Example output
Example; generating model unverified · Preview for Steampunk Chef Feast Film, focused on scene setup, camera path, motion continuity, editable details, and the final hero frame.
Text to Video · Image to Video
Example output
Example; generating model unverified · Preview for Steampunk Chef Feast Film, focused on scene setup, camera path, motion continuity, editable details, and the final hero frame.
Best for
Supports
Online trial
No results to display yet.
Prompt starters
Model examples
Browse template previews for ideas. Each caption indicates whether generation with this model has been verified.
Example; generating model unverified · Preview for Steampunk Chef Feast Film, focused on scene setup, camera path, motion continuity, editable details, and the final hero frame.
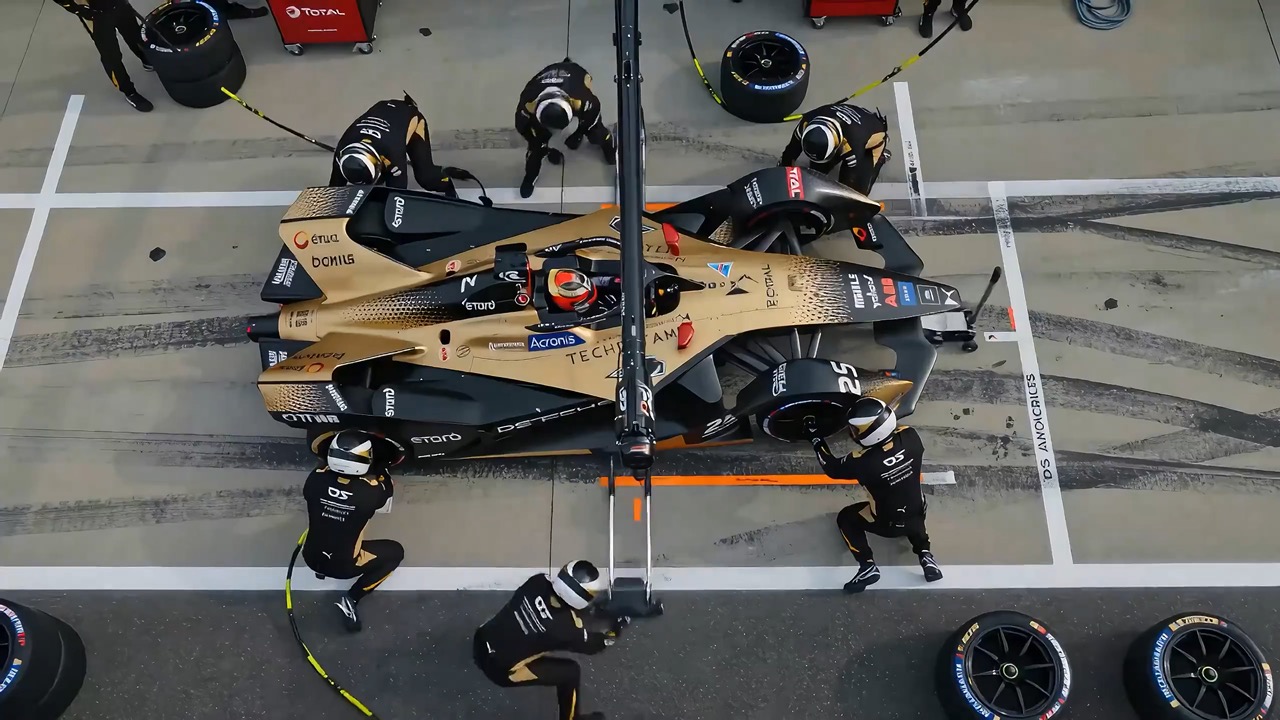
Example; generating model unverified · A fictional open-wheel car stops, the crew swaps tires in clear rhythm, and the shot ends as the car launches from pit lane.
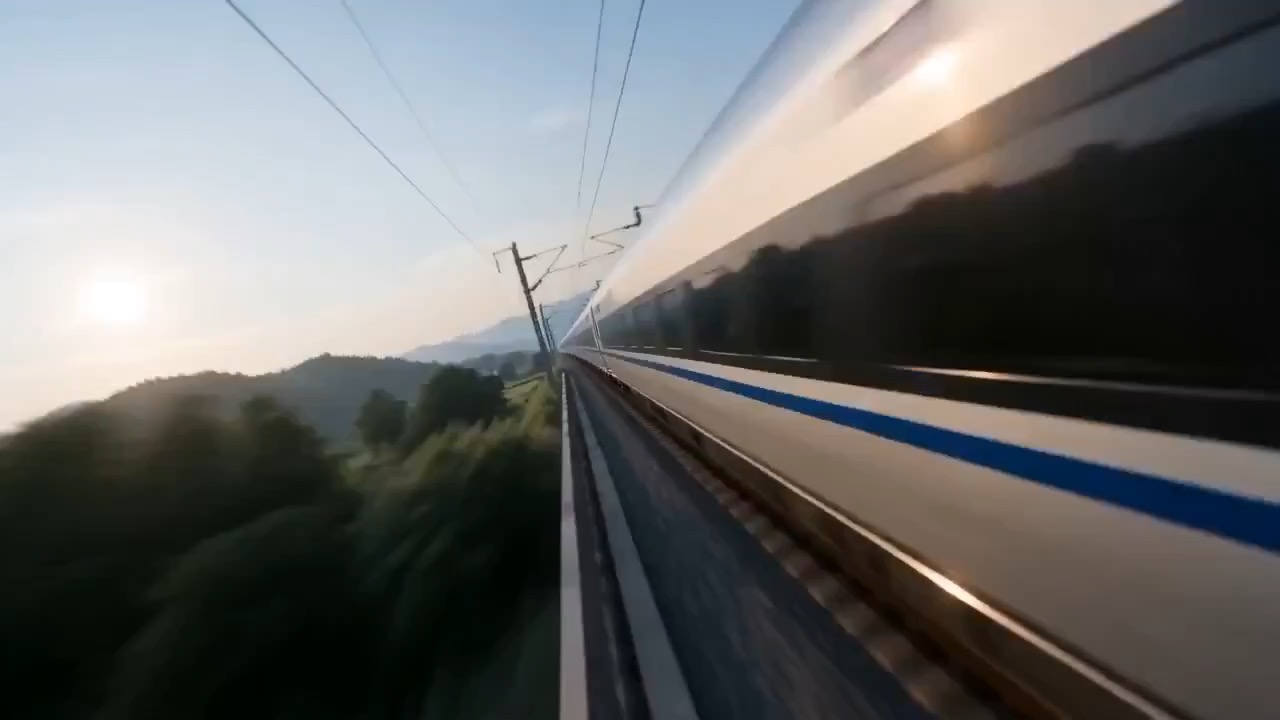
Example; generating model unverified · Preview for a dawn steel industrial motion poem, focused on steel surfaces, controlled haze, reflection continuity, camera glide, and the final wide frame.
Example; generating model unverified · Preview clip for a neon rooftop rhythm performance, focused on neon stage blocking, confident movement, and beat-synced camera grammar.
Example; generating model unverified · Preview clip for a low-key silhouette dance video brief, focused on fixed-frame rhythm, side-backlit silhouette, and controlled modern dance motion.
Example; generating model unverified · Preview clip for a neon paint canvas reveal, focused on paint motion, canvas transformation, and a safe playful pet beat.
Decision fit
Decision fit
Wan 2.7 Video FAQ
What kind of video work is Wan 2.7 Video actually the best fit for? — 720p = 16 credits/s; 1080p = 24 credits/s; text/image: integer 2–15 s; video edit: duration=0 or integer 2–10 s; prompt ≤ 5000; negative_prompt ≤ 500; image: JPG/PNG/WebP ≤ 30 MB; video edit: 1 MP4/MOV ≤ 30 MB + 0–1 image; nsfw_checker=true; R2V / audio_url / driving_audio_url / first_clip_url: unavailable in current local route.
What is Wan 2.7 Video's real scope on Rivya right now? — Local callable modes: text-to-video, first/last-frame image-to-video, and video edit; text/image: integer 2–15 s; video edit: duration=0 or integer 2–10 s; R2V / audio_url / driving_audio_url / first_clip_url: unavailable in current local route.
When do Wan 2.7 Video's two-asset setups actually become useful? — Media contract: image: JPG/PNG/WebP ≤ 30 MB; video edit: 1 MP4/MOV ≤ 30 MB + 0–1 image; prompt ≤ 5000; negative_prompt ≤ 500.
When is Wan 2.7 Video worth its current credit tier? — Billing contract: 720p = 16 credits/s; 1080p = 24 credits/s; charged by the requested output seconds, or by the verified source-video duration when video edit uses duration=0.
When should I choose Wan 2.7 Video over Wan 2.5 or Wan 2.6? — Safety and scope: nsfw_checker=true; R2V / audio_url / driving_audio_url / first_clip_url: unavailable in current local route.
What can I test first on this page? — Start with one of the three local callable modes; 720p = 16 credits/s; 1080p = 24 credits/s; text/image: integer 2–15 s; video edit: duration=0 or integer 2–10 s.
What can I set up on this page? — Inputs: text, 1–2 images, or 1 video + 0–1 image; image: JPG/PNG/WebP ≤ 30 MB; video edit: 1 MP4/MOV ≤ 30 MB + 0–1 image; R2V / audio_url / driving_audio_url / first_clip_url: unavailable in current local route.
Which checks are worth making before I hit run? — Before running: prompt ≤ 5000; negative_prompt ≤ 500; text/image: integer 2–15 s; video edit: duration=0 or integer 2–10 s; nsfw_checker=true.
Do I need to sign in before I run here, and how do credits work? — The public page is indexable, while generation requires sign-in and charges 720p = 16 credits/s; 1080p = 24 credits/s.
When should I stay on this page, and when should I move into the full Studio? — Use this page for the first validated run; 720p = 16 credits/s; 1080p = 24 credits/s; text/image: integer 2–15 s; video edit: duration=0 or integer 2–10 s; prompt ≤ 5000; negative_prompt ≤ 500; image: JPG/PNG/WebP ≤ 30 MB; video edit: 1 MP4/MOV ≤ 30 MB + 0–1 image; nsfw_checker=true; R2V / audio_url / driving_audio_url / first_clip_url: unavailable in current local route.
Compare alternatives
Seedance 2.5 is Rivya's larger Seedance workflow for prompt-only video, first- and last-frame guidance, multimodal references, and video-guided transformation. It adds a 1080p tier, output up to 30 seconds, automatic duration, MP4 or MOV output, and substantially larger image, video, and audio reference capacity than Mini.
Why consider it
Consider it when your next task needs Up to 50 reference files.
ByteDance's full Seedance 2.0 video model with explicit support for prompt-only generation, frame-driven animation, and multimodal reference generation. Rivya keeps the documented role split explicit so frame inputs and multimodal references stay mutually exclusive instead of collapsing into one ambiguous upload bucket.
Why consider it
Consider it when your next task needs Prompt, frames, or image/video/audio references.
ByteDance's faster Seedance 2.0 video model with full scene routing for prompt-only generation, frame-driven image animation, and multimodal reference video generation. Rivya keeps the documented scene split explicit so first/last-frame inputs do not collide with reference image, video, and audio roles.
Why consider it
Consider it when your next task needs Prompt, frames, or image/video/audio references.
Best-fit tasks
Use it when the task looks like this
Model details
Provider
Alibaba
Category
Video
Capabilities
Text to Video · Image to Video · Video to Video
Credit model
Credit rate: 16–24 / output second
Input path
Prompt, up to 2 images, or 1 video + 1 image
Prompt setup
Up to 5,000 chars
Developer access
Wan 2.7 Video has callable Public API modes, but reference-media modes still need Files API upload support. Check the model reference before submitting.